Explore AI
What Q4 actually costs you
Compression is the reason local AI exists. It is also the reason your local model feels dumber than the benchmarks promised.
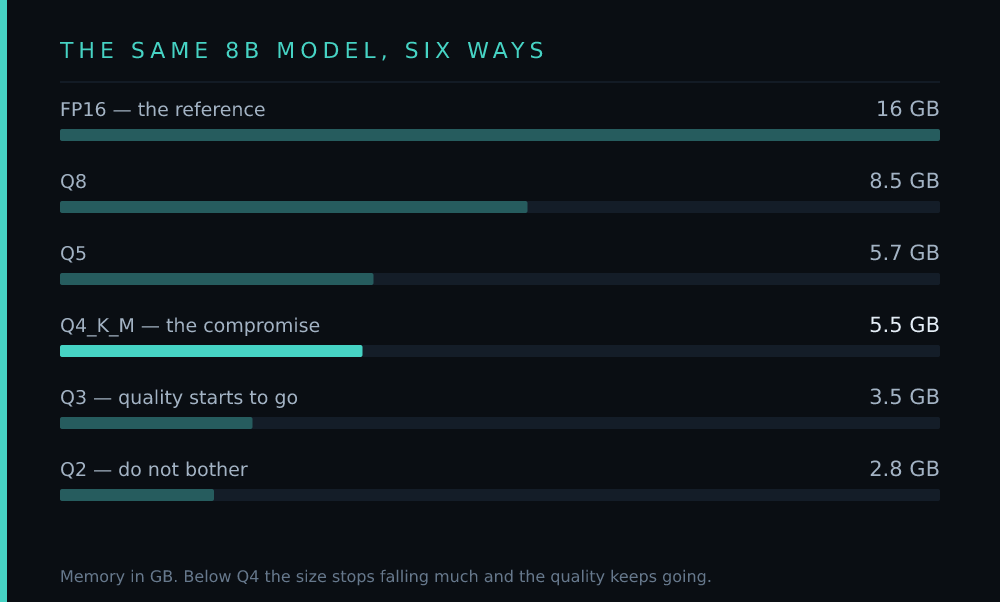
A model is a very large pile of numbers. Quantisation stores those numbers with fewer bits each, which is the only reason any of this fits on hardware you own.
The trade is simple to state and widely misunderstood in practice.
The scale
| Format | Bytes per parameter | 8B model | What it gives up |
|---|---|---|---|
| FP16 | 2 | ~16 GB | nothing — this is the reference |
| Q8 | ~1 | ~8.5 GB | almost nothing measurable |
| Q5 | ~0.7 | ~5.7 GB | very little |
| Q4 | ~0.55 | ~5.5 GB | the standard compromise |
| Q3 | ~0.43 | ~3.5 GB | noticeable, especially on reasoning |
| Q2 | ~0.35 | ~2.8 GB | quality collapses |
Q4 is the default for a reason. Above it you are spending memory for very little gain; below it you are spending quality for very little saving. The specific variant matters too — `Q4_K_M` is the one usually worth choosing.
Two things benchmarks will not tell you
Degradation is not uniform. Quantisation does not make a model uniformly slightly worse. It tends to hurt reasoning and instruction-following far more than it hurts fluency. A Q3 model can still write a fluent paragraph while failing to follow a three-step instruction — which is why it is easy to be fooled.
Published scores come from full-precision models. When a model card claims a benchmark result, it was almost certainly measured at FP16 or BF16. Your Q4 copy will score lower on exactly the tasks you care about, and there is no way to know by how much without testing it yourself.
The KV cache, which nobody mentions
The weights are only half the memory story. The KV cache is the model's working memory of your conversation, and it grows with context length. On a long document, the cache can exceed the weights.
This is why a model that "fits" on your hardware struggles with a long PDF: the weights fit, and the conversation does not.
Practical levers: cap the context length, and prefer models designed for long context rather than forcing it.
What to do about it
1. Start at Q4_K_M. Only go lower if the model genuinely will not fit. 2. If quality seems poor, try Q5 or Q6 before blaming the model. The difference is often the quantisation, not the weights. 3. Test on your own task. A model that scores well on a leaderboard and badly on your work is not a good model for you.